Framework for 3D Reconstruction Understanding
3D Computer Vision Practical Course, Technical University of Munich ·
Supervisor Prof. Federico Tombari
TL;DR
- Problem
- Which paradigm — hybrid, feed-forward or self-supervised — best recovers camera poses and geometry from unposed RGB images, and what does the strongest model actually rely on?
- Approach
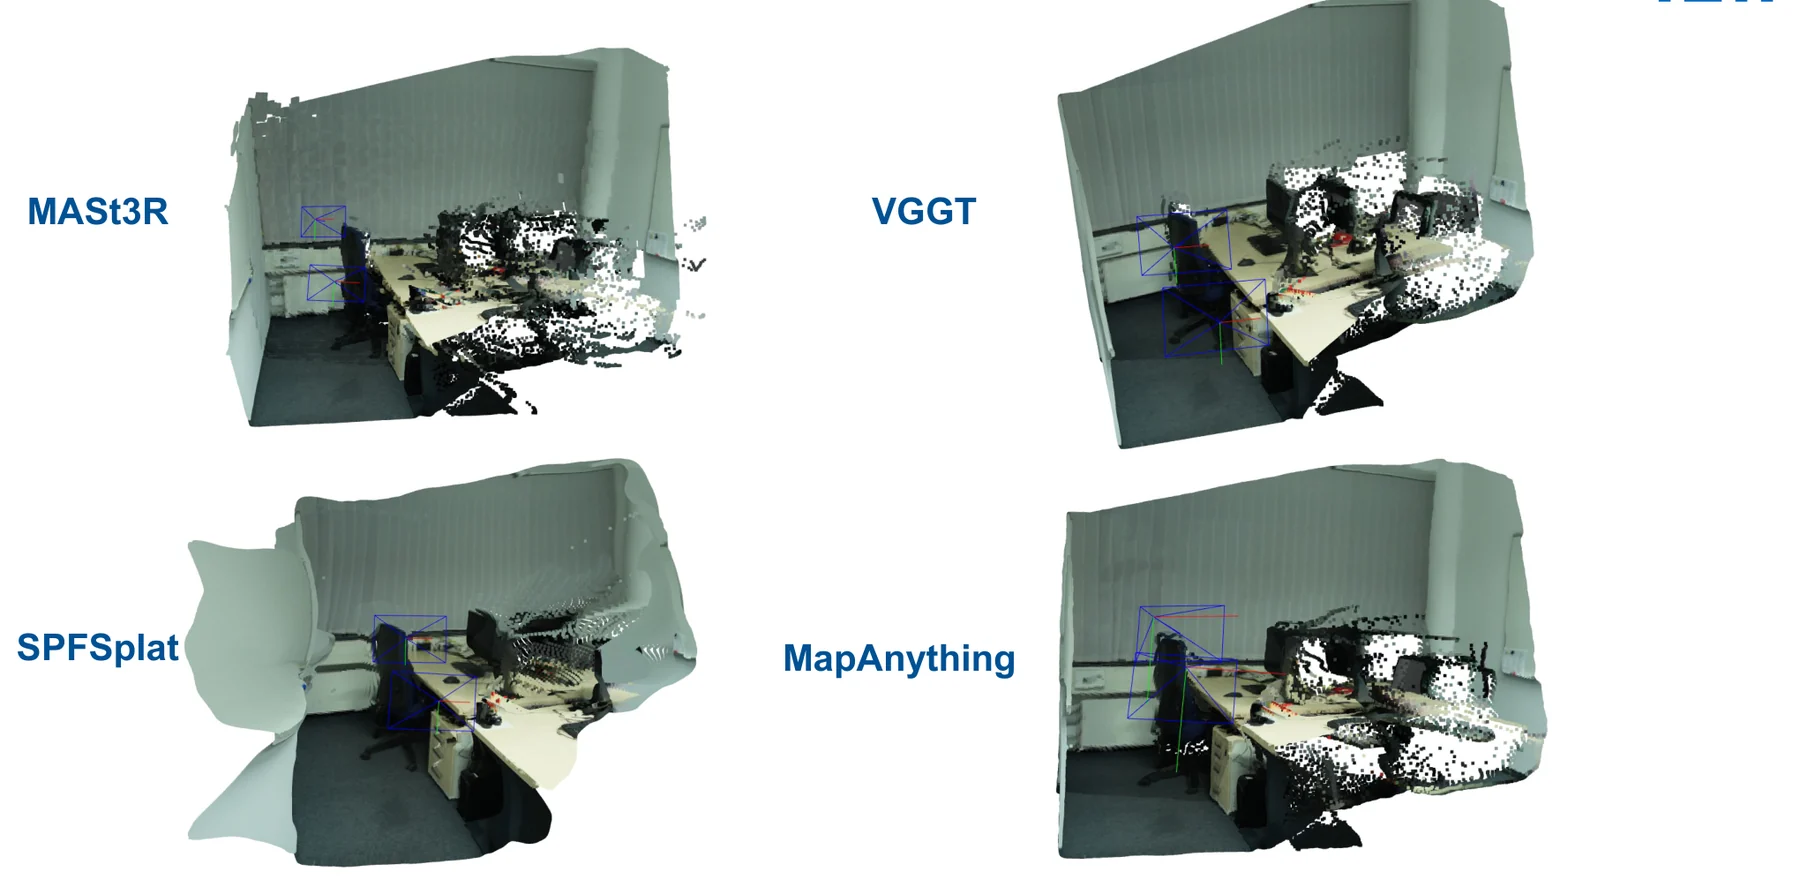
- Benchmark MASt3R, VGGT, MapAnything, SPFSplat and RayZer on ScanNet++ with 2–16 views, then analyse MapAnything with input ablations (images, depth, intrinsics, poses), robustness tests (photometric noise, depth masking, calibration noise) and interpretability tools (attention and feature maps, Grad-CAM, saliency).
- Findings
- MapAnything leads in every setting (74–79% pose AUC@5° from RGB alone), while the self-supervised methods reach near-zero pose accuracy. Known poses lift AUC@5° from 74% to 96%, but just 10% calibration noise drops it to about 50% — bad priors are worse than no priors.